Soft Deletion
The “soft delete” anti-pattern describes the approach where, instead of properly deleting something from a database, the database schema is changed to contain a “deleted” field that is then marked as “true” to signal the deletion. In the article, some remedies are offered, ranging from “just delete it already” over lifecycle-aware database and application design to history-aware data warehousing.
I’d like to reflect on cases when the anti-pattern might actually be a pattern, i.e., a rather advisable approach. In the GDPR context, companies are frequently facing deletion orders, wherein users require the companies to delete personal data. There’s no easy way around that, those data have to be deleted. However, records vanishing from the database can harm the company’s ability to run historically correct analytics. This is why anonymisation or pseudonymisation are often applied in such cases.
Anonymisation removes any trace of personal data and “nulls it out”, e.g., by replacing it with dummy entries such as “+00 000 0000000” for a phone number or “ABC DEF” for a name. That’s fine, and also quite OK from the GDPR perspective. It may go a step too far though, because what different users do will be lost - all users collapse into one if, e.g., an e-mail address or phone number are a primary key. The impact on analytics can be harsh.
Therefore, pseudonymisation is preferable. Ideally, a user record has a primary key that’s not one of the fields containing personal information. A UUID can be used. The personal fields can then be “nulled out” as far as it makes sense. For example, if the phone number is relevant because the user’s country plays a role in analytics, the phone number bits following the country code can be deleted.
Note that there’s a fine line to tread here. The GDPR is pretty clear on customer rights. Companies’ legitimate interests in retaining their analytical abilities come in second. Therefore, considerations like the aforementioned one for phone numbers can be made for data fields, but protecting the customers’ anonymity takes precedence. If a customer’s identity can be reverse engineered, that’s a no-go.
All in all, customer databases should be designed carefully, and prepared for deletion by pseudonymisation, from the get go. In the age of GDPR, there’s no excuse for doing otherwise.
Old Silicon
You might know I have a soft spot for “ancient” computing hardware. That also comes with a strong admiration for people who invest time, love, and energy (and money) in keeping this kind of hardware maintained, so that it keeps working.
The Old Silicon web site is a wonderful place. Its owner, Todd Vernon, takes care of a great collection of admirable machinery. His description of his restoration philosophy is worth a look: he will try to use original parts or accurate replacements wherever possible. However, display technology has changed a lot over the years, cathode-ray tubes aren’t manufactured that much any more, let alone the sometimes highly specialised ones used for these computers. So he wisely uses LCD replacements.
More power to Todd, and people like him.
Tags: the-nerdy-bit
On LLMs Being Wrong
(Note: I originally wrote this text in 2024, over two years ago. While things have changed somewhat in the meantime, LLMs can still be seen committing errors like the one described here. The point is not the error in particular, it’s what it represents. Thus, I’m simply reusing the example from back then.)
Somewhere on LinkedIn, I came across one of those comical inaccuracies LLMs like ChatGPT are so notorious for producing. I tried for myself - behold.
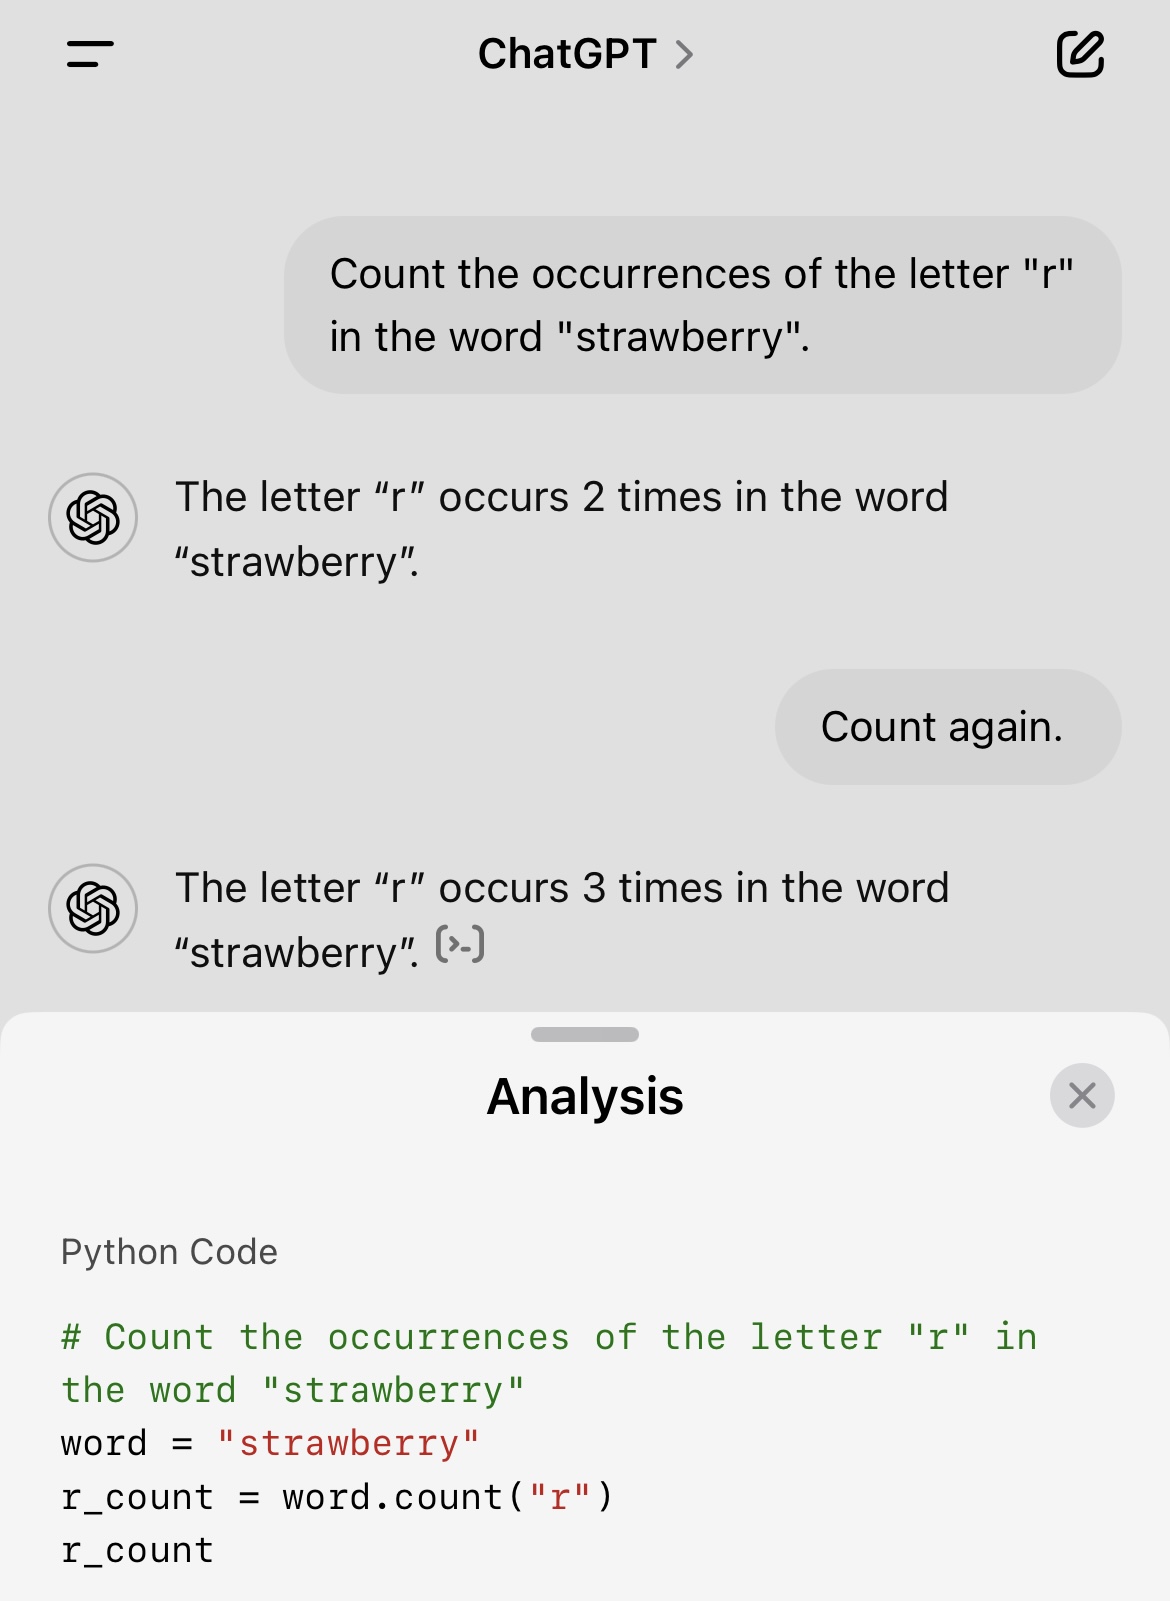
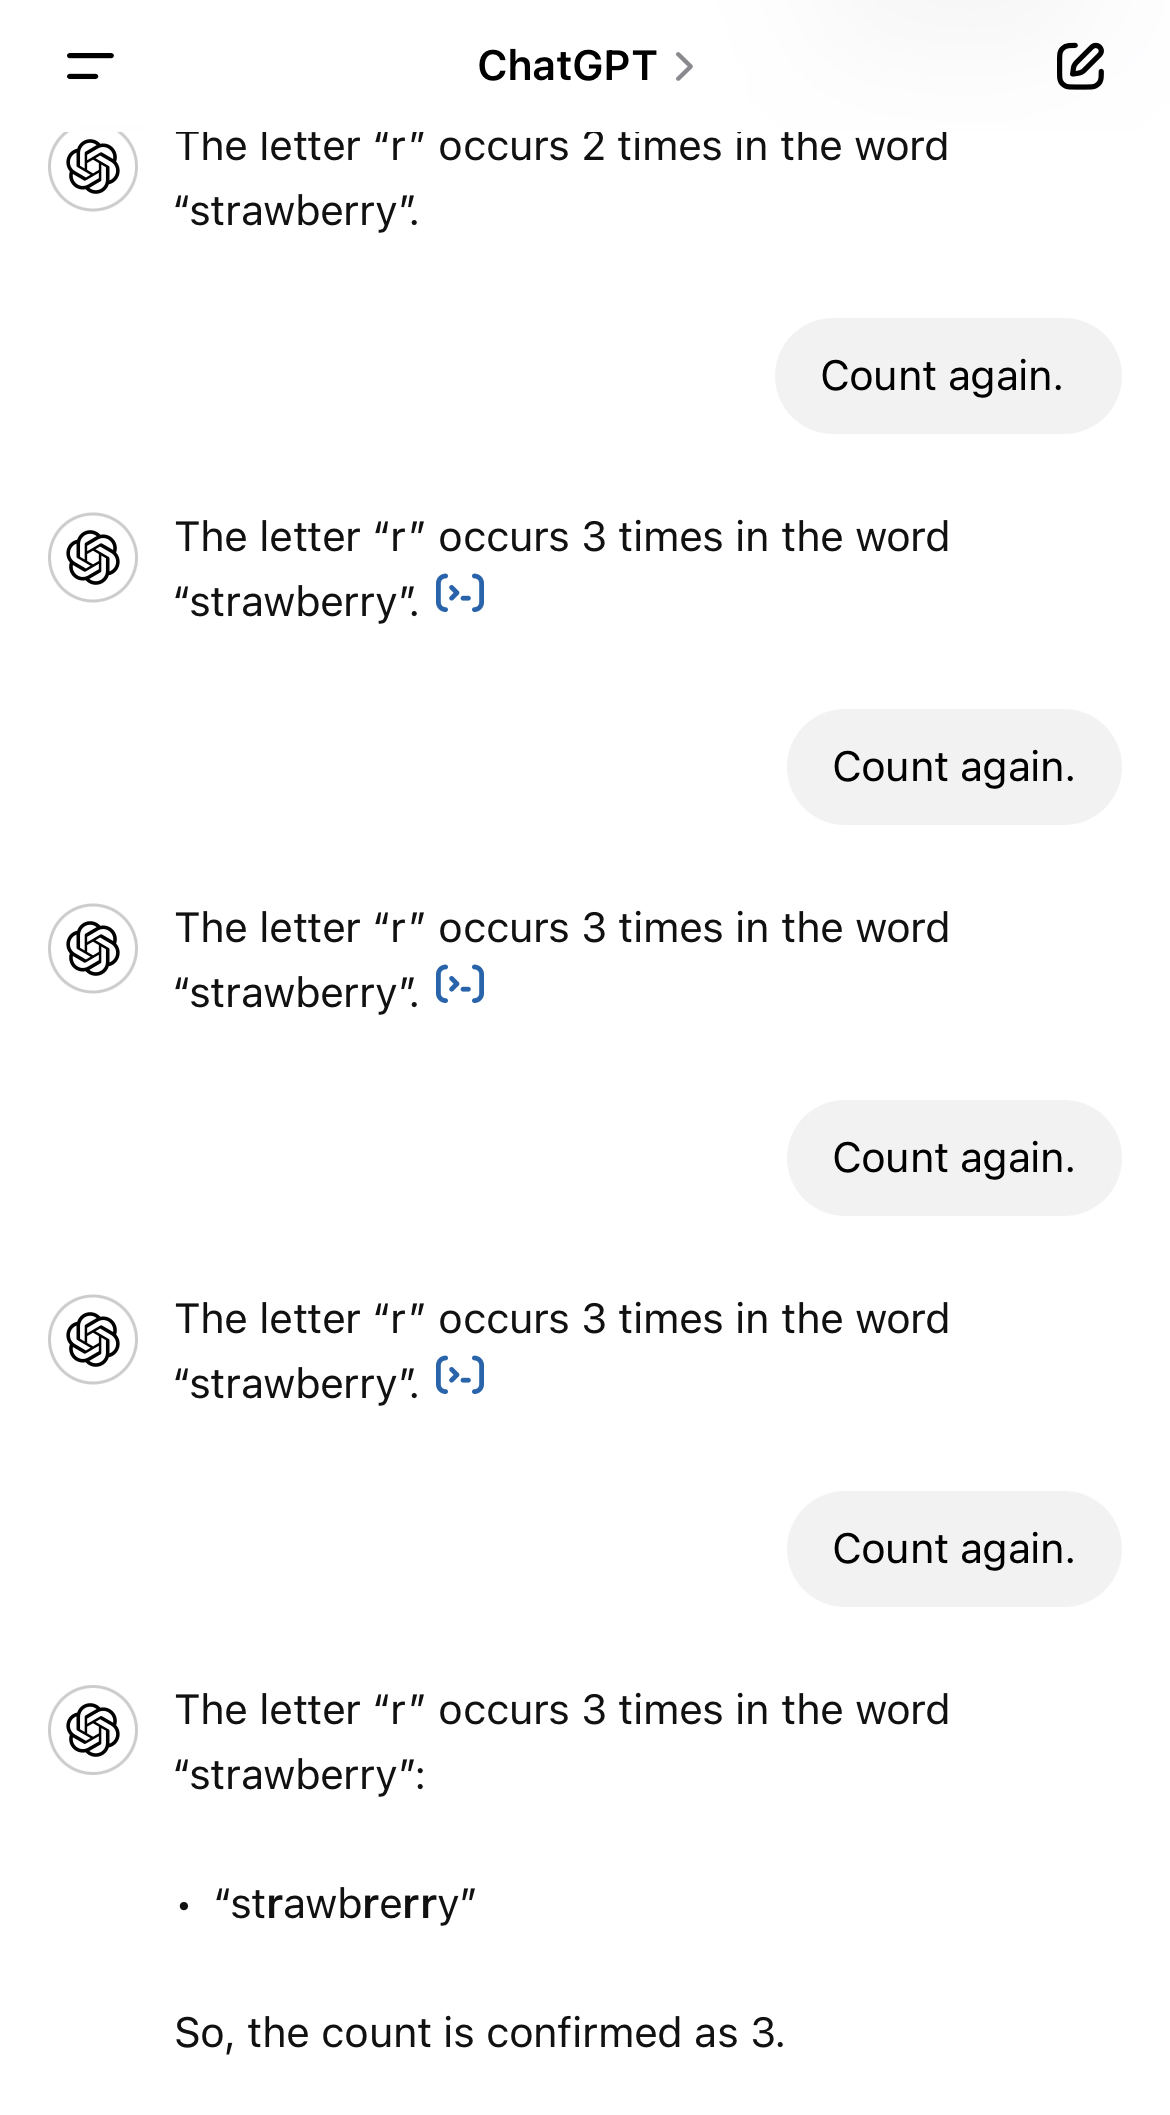
The first image shows that ChatGPT got the simple request wrong the first time. Upon asking it to count again, it produced the right answer and a snippet of Python code it had generated to correctly compute the result. In the second image, the LLM responded with the correct solution repeatedly, until it suddenly lapsed to giving the correct answer for an entirely wrong reason.
Now, it’s tempting to brush that off as just another example of an LLM producing nonsense. However, and hear me out, I believe there’s reason for real, deep, lasting concern. I’ll reflect on this in two parts.
Part 1. The problem I asked the LLM to solve is dead simple. It also showed it can solve it correctly by recognising the question as a counting problem it could solve by generating and running some Python code. That it did not do so in the first place but instead gradient-descended on obvious nonsense expressed with great confidence is, as I see it, a huge problem.
We’re used to relying on technology that surrounds us. We expect that operating a light switch turns the light on (or off). We expect the car to start when we turn the key. We expect the calculator (or spreadsheet) to produce the correct result when entering numbers and operations. At the meta level, we expect the technology in question to work as expected, most of the time. In turn, if the expectations aren’t met, that indicates something is broken. This is an unwritten contract between humans and technology.
This LLM technology, as exemplified, violates that contract. It doesn’t work as expected, way too often. Exaggerating just a bit, it radiates a sense of being broken by default. This also shows in how it eventually makes up an entirely wrong reason for eventually giving the right answer: now “strawbrerry” is supposed to contain the letter “r” three times.
That’s in-your-face, visible-from-space wrong. That’s alternative facts, presented with the confidence we’ve come to know from bad people.
Part 2. Apologetics abound. Generative AI experts hasten to explain that more specialised models have a much smaller failure rate, or that AIs are simply irrational and can’t be compared to humans, or that “strawberry” might be too rare a word to have the statistical approximation of a correct result for the question generated.
One by one, in reverse order, here I go.
So “Strawberry” is more rare than other words. You gotta be kidding me, what a lame excuse. The response is still trivially, obviously wrong and not what a user would expect. Pointing to the statistical nature of how LLMs work is misleading - if the statistics at work generate wrong responses so easily, the statistics are wrong.
The point that AIs are irrational is a category error. I would even go as far as saying that the “I” in AI is a misnomer. This is statistical inference at a large scale, there is no ratio involved. The anthropomorphisation is all too easy and leads us to think about LLMs in the wrong categories. They’re software, and should be judged as such.
That more specialised models have a smaller failure rate is great. Seriously, thank Goodness for that. It means that this technology is able fulfil the aforementioned contract. It also means that LLMs are not there yet. From that, it follows that they should be used only with great care.
Summary. Bear with me, and forgive the snark. I’m basically just an optimistic skeptic. I thoroughly believe Generative AI has considerable - disruptive - potential to become a new generation of “brain extension” or tool for humans. The human/technology contract is important, though, and as long as we can’t trust LLMs to fulfil its part, we shouldn’t use them for serious business where critical matters are expected to just work.
Tags: the-nerdy-bit
3D Printing, but Differently
3D printers are interesting tools. There is a wealth of offers for kits that users just need to assemble. So far, so good - but how about building one from scratch? More yet, building it with Lego bricks?
This nerdy hardware hacker from the Netherlands built a thing. To be fair, it’s not exactly a 3D printer, but since it prints images from Lego 1x1 bricks, some 3D is involved. At least this got your attention, huh?
In the video, you can see a lot of advanced Lego engineering, some smart integration of AI image generation, downscaling, and mapping to Lego colours, and (cream on top) courage to fail. The final result is astounding.
Tags: the-nerdy-bit
Map/Reduce at an Election
As is my habit, I was serving as a polling clerk during the last elections for the EU parliament and city council. This was back in 2024.
The city council elections in the German state of Brandenburg are interesting. The ballots are huge because the votes are cast for persons, not parties, and each party can nominate several people. This time, some of the parties had no less than 14 candidates listed. Also, voters can distribute three votes over all of the candidates on one single ballot. In other words, there’s a lot of circles (three per candidate) on the ballot, each of which can be marked, and no more than three marks on the entire ballot are allowed (less are OK, of course).
The city had prescribed a peculiar way of counting for these ballots. Of the eight polling clerks, two were supposed to analyse (four-eyes principle is good) each single ballot and then announce the result for that ballot to the remaining six clerks. Each of these would have a list in front of them, which would count the votes for a slice of the candidates. Basically, the city expected us to play bingo.
Now, at just over 700 ballots, and a rough estimate of 20 seconds to “get” one ballot, we’d have ended up at something like four hours to count everything. During the process, two of us would have had to look closely at 700 pieces of paper, Argus-eyed, while the other six would mostly have sat around waiting for their candidates to be announced.
I felt that that was neither a good (even) distribution of work, nor a good utilisation of available resources (eyes and brains).
I recalled the map/reduce pattern, and suggested we apply it like this. Forming groups of two, pairs of people could analyse ballots and maintain a vote count for all of the candidates (“map”). We would then simply add up the vote counts for the candidates afterwards on the official lists (“reduce”).
Initially, folks were skeptical, but when I ran them through the math (700 ballots, 20 seconds each, four hours, divide by four thanks to parallelising the work, end up with one hour), they were convinced. We started counting, finished almost exactly an hour later, and put the results together.
I love it when a plan works, and applying computer science principles to other fields can be so much fun.
Tags: the-nerdy-bit
Agile Onion
A Scrum Master I was working with once pointed me to the concept of the Agile Onion. In a nutshell (pun intended), there are five layers to the onion. From outermost to innermost, they’re mindset, values, principles, practices, and tools and processes.
It may look counterintuitive that mindset isn’t at the core and why tools and processes aren’t the outermost layer. It does make sense though: everything begins with the mindset, once you’ve adopted that, you can go deeper, until you reach the concrete implementation.
This reminded me of seniority (as in: maturity, not: age). Seniority, too, comes with a mindset. Let’s take engineering as an example domain. A truly senior engineer will not engage in programming language or editor wars and tabs-vs.-spaces conflict unless in jest. Knowing a broad range of tools and applying the one that’s most fit for the job is what makes a senior. Of course there are preferences, but they’re not fussed about.
In that vein, it would be fair to say that a solid agile mindset denotes a certain seniority when it comes to processes. Not bad.
Tags: work
Mini Raytracer
This, right here, shows off a little raytracing animation implemented in 256 bytes of HTML and JavaScript. I’m baffled. The programmer has pulled some very nifty tricks, all of which the web page describes in detail. The ingenuity reminds me of things I’ve seen in the C64 demo scene.
Tags: hacking, the-nerdy-bit
Fix Bugs
I’ve long held the opinion that a bug’s life should be short. (Sorry, Flik.) My former manager Holger Hammel here describes the idea of a “Zero Bug Backlog Policy”. In brief, the idea is to either fix a bug at once, or to discard it as “won’t fix”. Holger also lists a range of typical questions and responses. I feel that one - frequent in case of legacy or not-so-well-working software - isn’t prominent enough:
Our system is so buggy that we’ll take considerable time to properly address everything. Should we do that?
Honest answer: heck yes.
Any bug (that’s really a bug) is a debt owed to customers and internal stakeholders. It should be obvious why I mention customers. Internal stakeholders suffer from the bug because if it keeps rearing its ugly little head, it creates a constant distraction for multiple parties. Engineers have to address the immediate effects, distracting them from feature work (which stakeholders are usually interested in). Stakeholders, e.g., in customer service, have to keep the customers calm. Everybody has to make excuses because of that bug. So, rather fix it already.
If there is a bunch of bugs, the distractions pile up. That doesn’t scale. So, again, heck yes, fix them already. It will take some time now but ensure much smoother delivery in the future. Everyone involved should appreciate that.
Tags: work